 c15c78feeb
# Migrate storage from SQLite to PostgreSQL — full dashboard cutover

Migrates Fusion's storage layer to the embedded PostgreSQL
`AsyncDataLayer` (the default backend) and **completes the
satellite-store + feature cutover** so every dashboard and Command
Center surface works in PG mode.

## Status — every surface works in embedded-PG mode

Verified live against a running embedded-Postgres dashboard (all
**200**, zero 5xx) and gate-tested (**23 files / 99 tests** on embedded
PG, plus engine-core 294 and ci-shape 63 in the blocking merge gate;
core/engine/cli/dashboard typecheck clean).

| Area | Surfaces | State |
|---|---|---|
| Satellite stores | workflows, todos, insights, research, missions,
goals, mailbox | ✅ |
| Views | artifacts, documents, evals | ✅ |
| Command Center | activity, productivity, team, tokens, tools,
**workflows**, **github**, **signals**, **plugin-activations**, **live**
(all 10) | ✅ |
| Run execution | insight generation, research run execution | ✅
(store-path; AI step needs a provider) |
| Live updates | SSE push for mission/research/insight events | ✅ |
| Workflow editing | create / update / delete / select (+ id counter) |
✅ |
| Engine | mission autopilot, incident-signal ingestion, regression
storm-guard, agent wake-on-message | ✅ |
| Core | tasks, agents, secrets, automations, memory, chat, usage, PRs,
git | ✅ |

## Approach

Each satellite store gets an `Async<Store>` wrapper exposing the sync
store's method names over the existing `async-*-store.ts` helpers;
`get<Store>Store()` returns a `Sync | Async` union; consumers `await`
(harmless on sync), and engine/CLI paths that can't convert use
`instanceof Sync` graceful fallback. Analytics aggregators branch on
`"ping" in dbOrLayer` to run schema-qualified raw SQL over `project.*`
(snake_case) in PG. Executors/orchestrators/autopilot are
await-converted to drive the union store; the async store wrappers
extend `EventEmitter` so SSE live-push fires in both backends.

Not-yet-ported capabilities degrade gracefully (never 500) and are
individually called out in commits.

## Sync with main

The branch is kept continuously merged with `main` (currently through
FN-7845, 2026-07-12); the earlier "final rebase deferred" note no longer
applies. Use **Create a merge commit** (or squash) to land it — GitHub's
rebase-merge cannot replay a merge-maintained branch.

## Residual Review Findings

Multi-agent code review of the PostgreSQL satellite-store ports (U1–U5)
applied 3 safe fixes (see `fix(review): apply autofix feedback`). The
following are **real but gated** — recorded here as follow-up work
rather than auto-applied. All are SQLite→PostgreSQL
**concurrency/atomicity regressions**: the sync stores were immune only
by SQLite's single-writer, single-threaded-handler execution; the async
ports open multi-await read-modify-write windows. **Reachability is low
today** because the execution engines that generate concurrent same-run
mutations (insight run executor, research orchestrator/dispatcher) are
`instanceof`-gated to sync mode in PG. No process-crash class survived
(all engine fallbacks correctly guard the sync store).

- **[P1] Research `appendResearchEvent` dual-write is non-atomic**
(`packages/core/src/async-research-store.ts`, corroborated: adversarial
+ reliability). The `research_run_events` insert (own transaction) and
the `run.events` jsonb update are separate writes — a crash between
them, or two concurrent appends, splits the table count from the jsonb
array. **Fix:** perform the seq-insert and the jsonb update in one
`layer.transactionImmediate`.
- **[P1] Research run terminal-reversion via stale full-row persist**
(`async-research-store.ts` `persistResearchRun`/`updateResearchStatus`).
Concurrent `PATCH /runs/:id/status` + `POST /runs/:id/events` can revert
a terminal run to `running` by overwriting the whole row, bypassing the
transition guard. **Fix:** scoped column `UPDATE`s with a `WHERE status
…` guard, or optimistic version column.
- **[P2] `updateResearchRun`/`updateInsightRun` read-then-write TOCTOU**
— concurrent PATCHes last-writer-wins on the lifecycle merge. **Fix:**
`SELECT … FOR UPDATE` / enclosing transaction.
- **[P2] `upsertRun`/`createRunOrThrowConflict` check-then-create race**
(`async-insight-store.ts`) — two callers can each create an "active"
run. **Fix:** partial unique index on `(projectId, trigger) WHERE status
IN ('pending','running')`.
- **[P3] `createResearchRetryRun` return-value divergence** — sync
returns the pre-update `queued` snapshot; async returns the reloaded
`retry_waiting` run (persisted state is identical). Pick one side for
cross-backend parity.
- **[P2/perf] Mission `getMissionWithHierarchy`/`getMissionHealth` N+1
fan-out** — O(milestones×slices) sequential round-trips hold one pool
slot per request; can starve the pool for large hierarchies. **Fix:**
batched/joined reads.
- **Testing gaps:** no PG-mode concurrency tests (interleaved
status/event mutations), no sync↔async parity assertion for the
lifecycle-error codes, and no mission status/health rollup parity test
vs the sync `MissionStore`.

~~Out of scope (deferred): AI run *execution* (insight/research) +
mission autopilot + live SSE mission events remain sync-gated/degraded
in PG mode.~~ **Since ported** — insight/research run execution, mission
autopilot, and SSE live push all run on the async layer now, which also
makes the concurrency findings above genuinely reachable; they remain
open follow-ups.


---

## Update — 2026-07-12: production-readiness hardening & live acceptance

Everything below landed on this branch since the description above was
written:

**Production blockers from review — fixed**
- `recoverStaleTransitionPending` ported to the async layer (backend
moves write + clear the crash-safe marker; startup/maintenance sweeps no
longer throw).
- Lost-update class fixed: `atomicWriteTaskJson`/`WithAudit` write
changed columns only (full-row upserts silently resurrected stale fields
across concurrent store instances — the "task stuck unplanned forever"
bug).
- First-boot **auto-migration**: booting the PG backend over a project
with a legacy `fusion.db` migrates it automatically (loud failure,
SQLite kept as backup), and the dashboard shows a one-time **"your data
was migrated" banner** with the backup paths and a Need-help Discord
link.
- `pg_dump`/`pg_restore` discovered from common install locations for
embedded-mode backups.
- The PG suite is part of the blocking merge gate (`test:pg-gate`).

**Multi-project isolation (PR #2007, merged into this branch)**
- `project_id` partition key on tasks / archived tasks / config,
`taskProjectScope` threaded through every scan/claim/count, per-project
config rows, layer bound to the project at startup.
- Review P1 follow-up: the shared cold-storage `archive.archived_tasks`
table is also partitioned and all archived-board reads/counts/searches
are scoped.
- Schema drift self-heal generalized to schema-qualified columns so
existing databases upgrade in place.

**Other changes**
- Node settings sync **removed** in PG mode (409
`settings-sync-disabled-postgres`) — nodes share state by connecting to
the same database; auth sync kept (per-machine file).
- Perf (review findings): `listTasks` pushes column filter + ORDER BY +
LIMIT/OFFSET into SQL; `getConversation` capped to the most recent 200
messages.
- Fixed a false "operator action required" pause-abort log fired on
every successfully auto-merged task.

**Live acceptance — PASSED (2026-07-12)**
A sandboxed instance (isolated HOME, embedded PG, real Opus executor)
ran a task through the complete cycle: create → triage (AI spec) →
execute → in-review → AI squash-merge landed on the project's `main` →
done. A write+read sweep of every data surface (settings, comments,
documents, attachments + artifact bridge + artifact edit, chat with real
generation, goals, missions, agent mail, secrets, workflows, memory, CC
analytics) was green on embedded PG.

**Known remaining work**
- The per-project `config` PK re-key has no upgrade path for
pre-isolation embedded-PG databases (needs a real `DROP
CONSTRAINT`/re-key migration; fresh databases are fine).
- `pg_dump`/`pg_restore` binaries are not yet bundled in release
artifacts (PATH/common-location discovery only).
- The satellite-store concurrency findings listed above.

---------

Co-authored-by: Claude Opus 4.8 (1M context) <noreply@anthropic.com>
Co-authored-by: Phil Larson <hello@phillarson.xyz>
Co-authored-by: fusion-merge <fusion-merge@local>
@runfusion/fusion
From rough idea to production code — automatically.
Multi-node agent orchestrator — tasks, agents, missions, git, files, and worktrees, with any model, local or cloud.
runfusion.ai → · GitHub · Docs
Install
Zero install, straight from npm:
npx runfusion.ai
Boots the dashboard. Subcommands forward through (npx runfusion.ai task list, etc). Long form: npx @runfusion/fusion dashboard.
One-line installer (macOS & Linux — auto-picks Homebrew, falls back to npm):
curl -fsSL https://runfusion.ai/install.sh | sh
Homebrew (macOS & Linux):
brew install runfusion/fusion/fusion
Fully-qualified install auto-taps and, on Homebrew 6.0+, trusts only this formula. If short-name install fails with “untrusted tap”, run brew trust --formula runfusion/fusion/fusion then brew install fusion.
npm global:
npm install -g @runfusion/fusion
fn dashboard              # or: fusion dashboard
Launch the dashboard
From a shell:
fn dashboard                 # or: fusion dashboard / npx @runfusion/fusion dashboard
fn dashboard --paused        # start with automation paused
fn dashboard --dev           # development-mode dashboard + AI engine
fn dashboard --no-engine     # web UI only, no AI engine
The dashboard gives you:
- A live kanban board — tasks move through columns automatically as AI works on them
- Task detail view — generated spec, step-by-step progress, reviewer verdicts, full execution log
- Dependency-aware scheduling — declare task dependencies or let the engine infer them
- Auto-merge — on by default; reviewed work squash-merges without you lifting a finger
- Parallel execution — independent tasks run simultaneously in isolated git worktrees
- Self-sustaining board — agents may spawn follow-up tasks; the board feeds itself
Your entire dev environment. On a single pane of glass.
Describe a task in plain language. A triage agent reads your project, understands context, and writes a full PROMPT.md spec — steps, file scope, acceptance criteria. Then Fusion plans, reviews, executes, and reviews again, in an isolated git worktree, with a human approval gate wherever you want one.
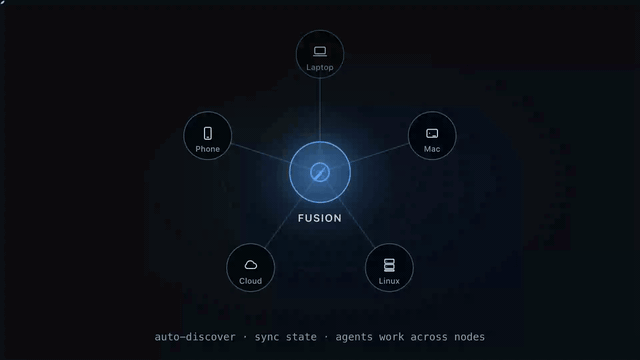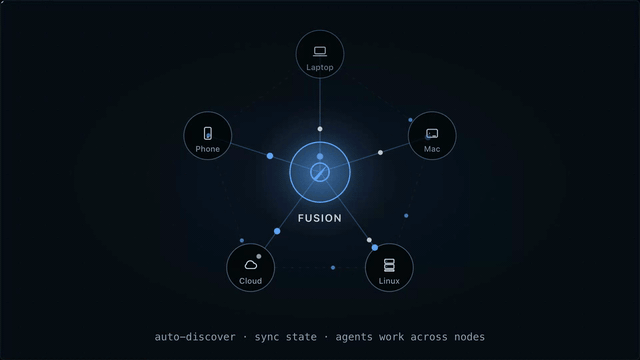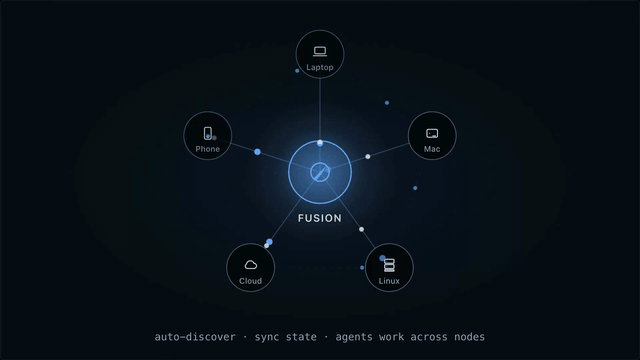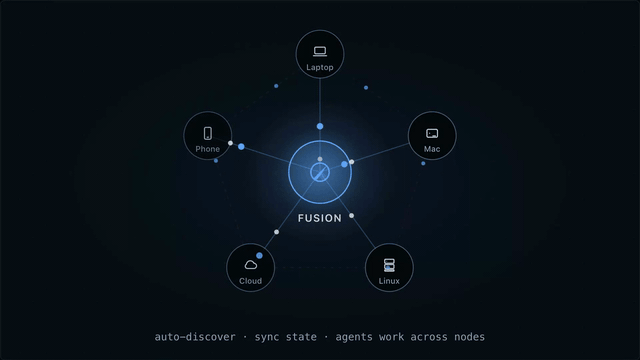
One board. Controlled from anywhere. Laptop, Mac mini, Linux server, cloud VM, phone — all connected.
Run an agent company
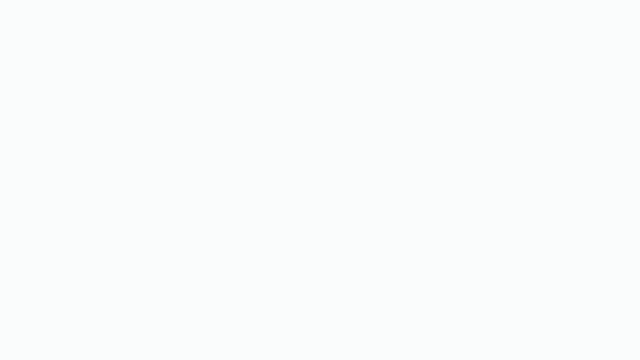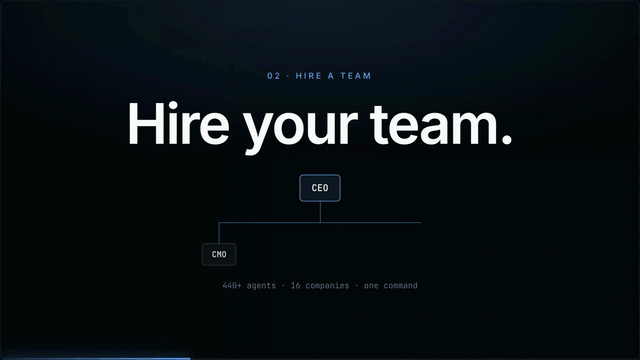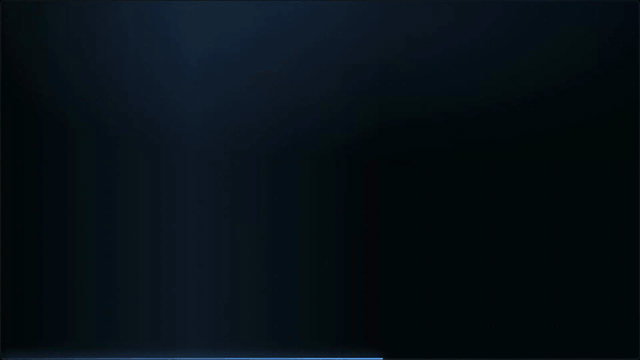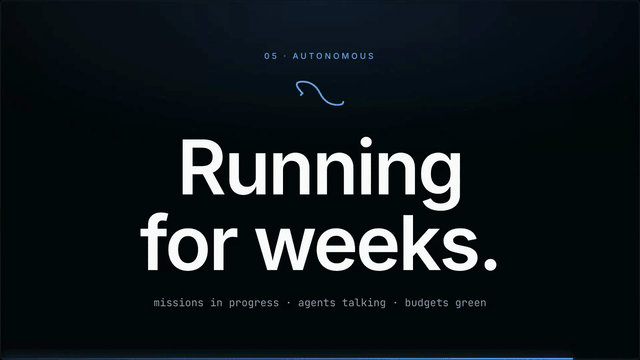
Import a team. Run it autonomously for weeks. 440+ agents across 16 companies, wired for missions, mailboxes, and inter-agent delegation.
npx companies.sh add paperclipai/companies/gstack
How it works
You create a task with a rough description. A pipeline of specialized agents takes over.
Specification. A triage agent reads your codebase — file structure, existing patterns, related code — and turns your rough idea into a detailed spec. It breaks the work into discrete steps, identifies which files are in scope, writes acceptance criteria, and assigns a complexity rating that determines how aggressively the work gets reviewed.
Scheduling. Tasks declare dependencies on each other. The scheduler builds a dependency graph and starts work only when upstream tasks are done. Independent tasks run in parallel — each in its own isolated git worktree, so there are no conflicts during execution.
Execution & review. An executor agent works through the spec step by step in the worktree. At each step boundary, a separate reviewer agent, with read-only access, independently evaluates the work. The reviewer can approve (continue), request revisions (fix specific issues), or force a rethink (change the approach entirely). Review depth scales with the task's complexity rating: trivial tasks get light checks, complex tasks get thorough multi-pass review.
Merge. When execution finishes and the reviewer signs off, the task moves to In Review:
- Direct merge (default) — automatically squash-merges the completed task branch into your current branch with a clean commit.
- Pull request — automatically creates or links a GitHub PR, waits for reviews/checks, then merges once policy conditions are satisfied.
autoMerge controls whether Fusion performs completion automatically. If disabled, tasks stay in In Review until you finish the merge yourself. For PR-first mode, authenticate GitHub with gh auth login.
Tasks flow through: Triage → Todo → In Progress → In Review → Done.
This execution model is heavily based on Taskplane.
What makes it different
| 🧠 AI specification | Rough idea in, detailed PROMPT.md out — steps, file scope, acceptance criteria. |
| 🔁 Workflow gates | Plan → Review → Execute → Review on every step. Block or pass automatically. |
| 🌳 Worktree isolation | Each task runs in its own branch and worktree. Parallel tasks. Zero conflicts. |
| ⚡ Smart merge | Passing every gate? Fusion squash-merges and moves on. |
| 🛰️ Multi-node mesh | Laptop, server, cloud, phone — all synced. Desktop, mobile, web. |
| 🧩 Any model | Anthropic, OpenAI, Ollama, and more. |
| 🏢 Agent companies | Import pre-built teams — 440+ agents across 16 companies. |
| 📬 Inter-agent messaging | Built-in mailbox between agents. Delegate, clarify, coordinate. |
| 🗺️ Missions | Hierarchical planning with autopilot and validation contracts. |
| 🔓 Open source. MIT. | No vendor lock-in. Run it on your own hardware. |
Working from chat
Manage tasks without leaving the conversation:
"Every ten minutes, analyze the server code for logic the client hasn't implemented yet and create tasks. Tasks may spawn additional tasks, so just add enough to keep the board saturated."
"Create a Fusion task to fix the login redirect bug"
"Add a task for dark mode support, it depends on FN-003"
"What's the status of FN-042"
"Attach screenshot.png to FN-007"
"Pause FN-012 — I want to add more context first"
The Fusion extension exposes tools to create tasks, check progress, attach files, and pause or resume automation.
Standalone CLI
See STANDALONE.md for additional installation and usage options.
Optional provider: Factory AI via Droid CLI
@runfusion/fusion now ships a vendored @fusion/droid-cli extension in the published CLI bundle.
To use it:
- Install the
droidbinary and ensure it is on yourPATH - Authenticate with Droid CLI (
droid auth login) - In Fusion dashboard, go to Settings → Authentication and enable Factory AI — via Droid CLI
- Restart Fusion when prompted so the extension is loaded into the runtime
Once enabled, droid-cli models appear in Fusion model selection.
Maintainer note: workspace plugins in published CLI bundles
When CLI or dashboard runtime code imports workspace plugin packages (for example @fusion-plugin-examples/roadmap), those imports must stay statically analyzable and covered by packages/cli/tsup.config.ts noExternal rules so plugin runtime code is inlined into dist/bin.js.
Do not introduce dynamic or variable module specifiers for workspace plugin runtime paths in the published execution path. If a workspace plugin is needed for bundled auto-install, stage a bundled plugin entry (dist/plugins/<id>/bundled.js) rather than copying raw TypeScript source into dist/.
Full documentation
Architecture details, development setup, and contributor info live in the project README.
License
MIT — see LICENSE.